Junha Jung

Korea University · DMIS Lab
Hello! I am an M.S. student in Computer Science at Korea University, advised by Prof. Jaewoo Kang at the DMIS Lab. Previously, I worked as a research assistant at Yonsei University and as an AI Consultant at Deloitte Consulting.
My primary research interest lies in Multimodal Reasoning, focusing on Reinforcement Learning, Visual Representation Learning, and Visual Grounding. My research spans Medical MLLMs and general-purpose multimodal models, with particular attention to improving reasoning and the use of visual information.
I am interested in developing multimodal models that can reason reliably across diverse visual tasks. Building on my research in medical visual question answering, I aim to explore broader challenges in multimodal reasoning, particularly how models learn to reason and how visual information is represented and utilized.
News
| Oct 2026 | Our paper Breaking Failure Cascades was accepted to EMNLP 2026 Main! 🎉 |
|---|---|
| Sep 2026 | New preprint! Reason Through the Latent! is now available on arXiv! |
| Jul 2026 | We presented CLAG at ACL 2026 Findings in San Diego, USA! 🎉 |
Publications
All publications- Figure coming soonPreprint 2026MedQual: Reframing Medical Visual Question Answering Through Data QualityPaper coming soon
-
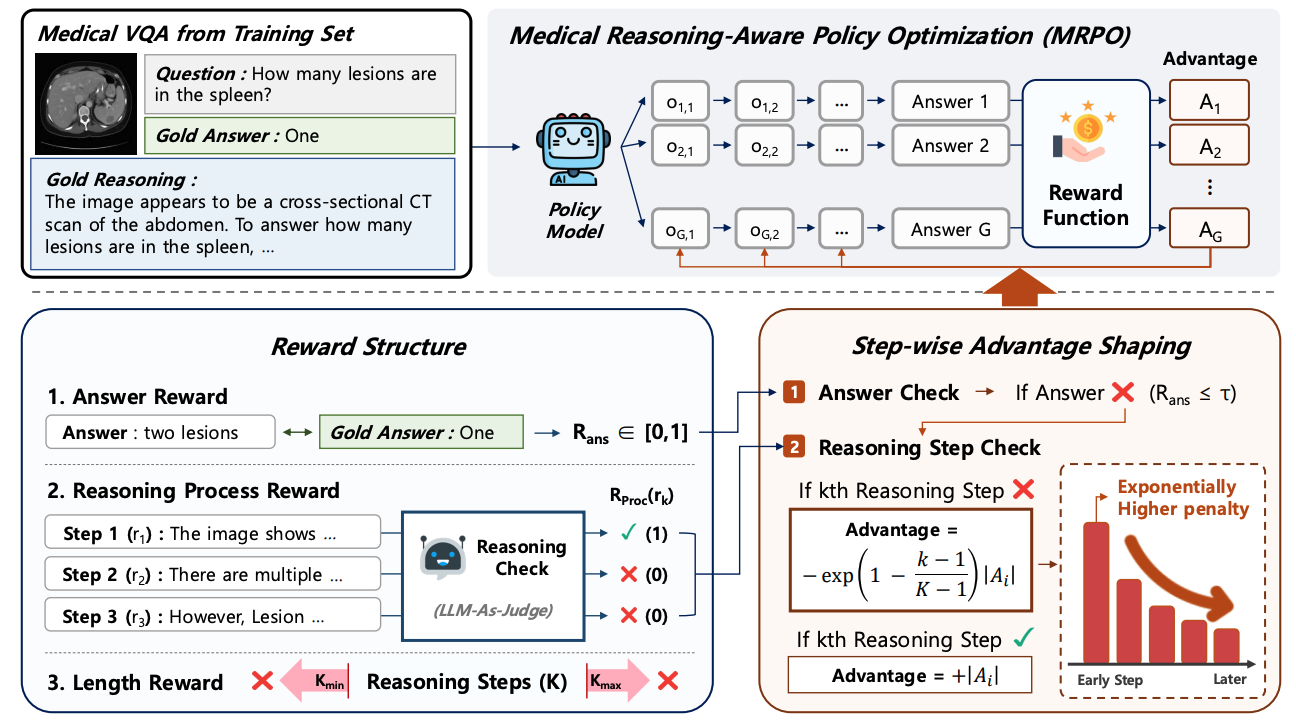 EMNLP 2026Breaking Failure Cascades: Step-Aware Reinforcement Learning for Medical Multimodal Reasoning (MRPO)
-
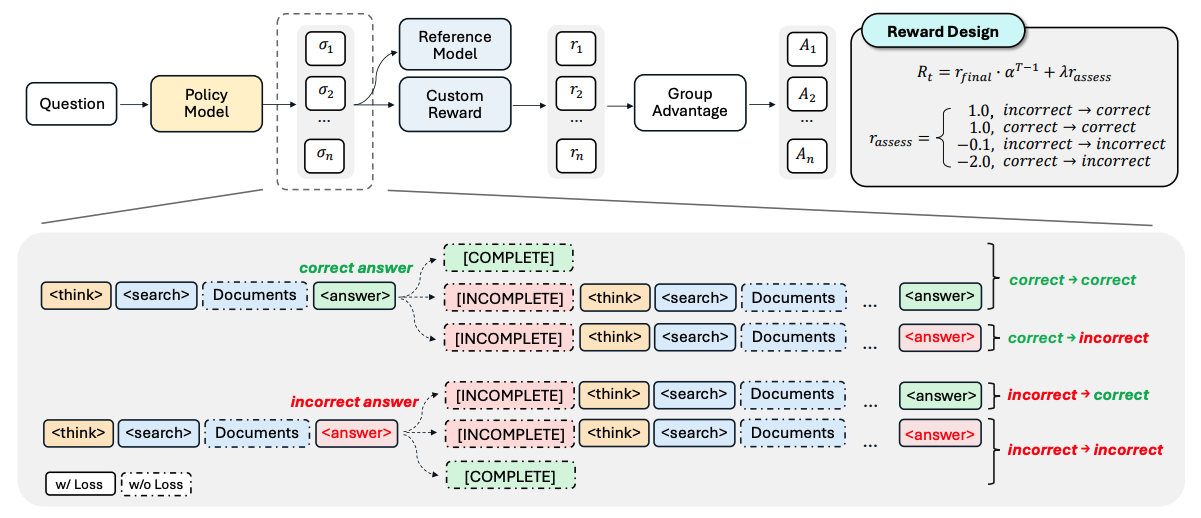 Preprint 2026Self-Assessment Reinforcement Learning for Search-State Awareness in Retrieval-Augmented Large Language Models
-
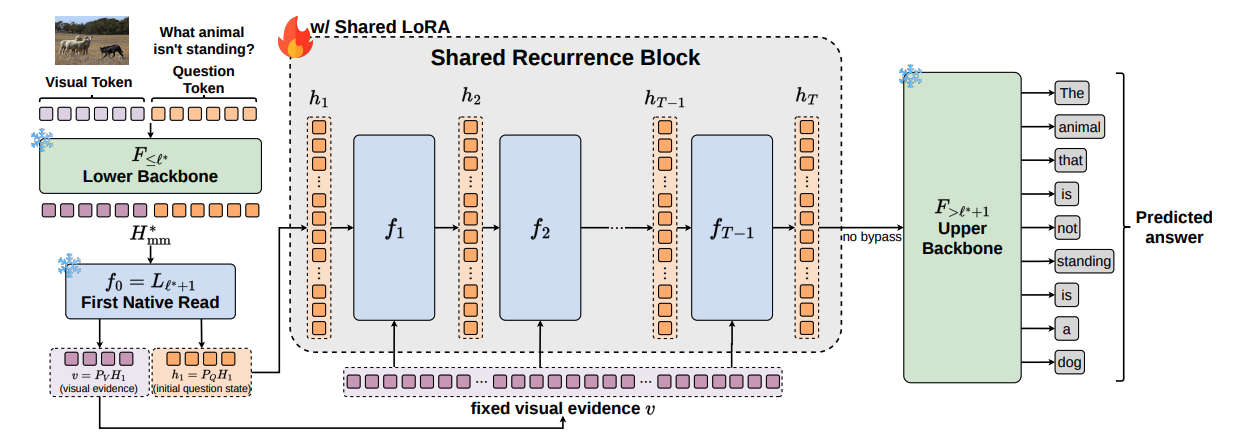 Preprint 2026Reason Through the Latent! Making Latent Visual Reasoning Necessary
-
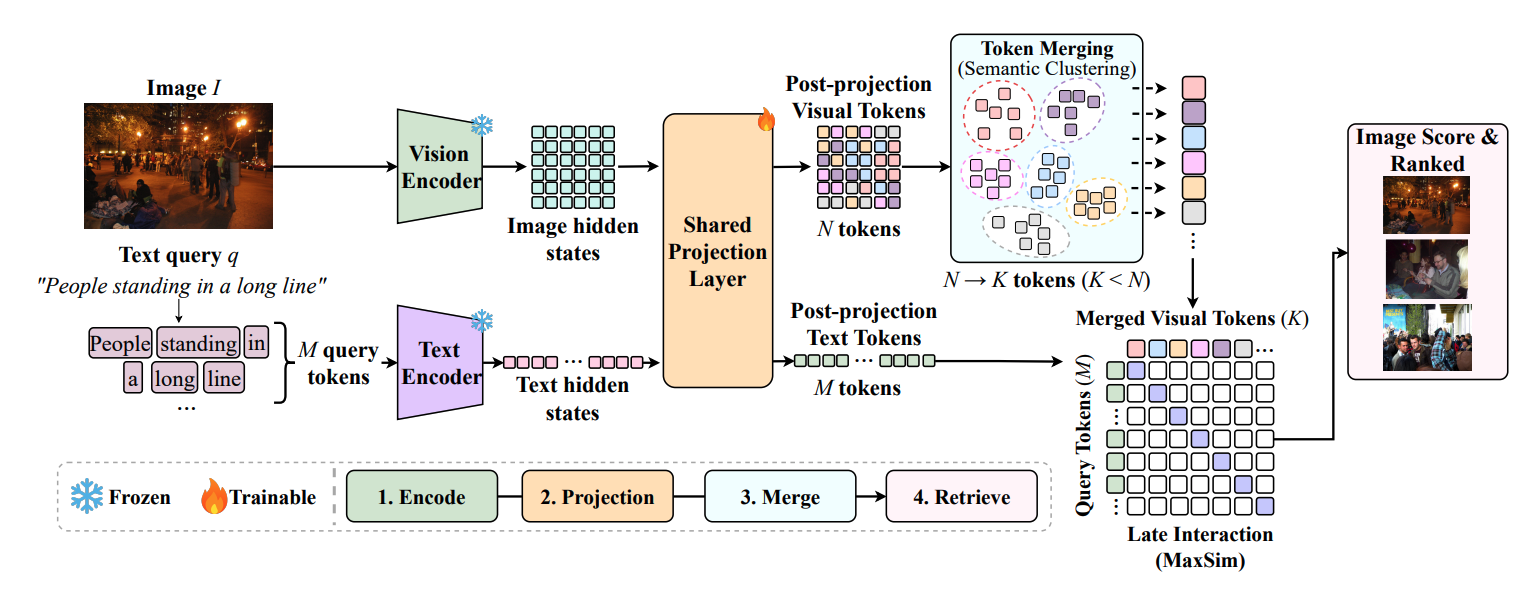 Preprint 2026Do All Visual Tokens Matter Equally? Object-Evidence Preserving Token Merging for Vision-Language Retrieval
* Equal contribution.
Research Interests
Multimodal Reasoning
How can we improve multimodal reasoning through better learning and reasoning processes?
Visual Representation & Grounding
How can models preserve and utilize visual evidence for grounded reasoning?
Medical MLLMs
How can we improve the reliability of medical MLLMs through better reasoning and data?